Simplifying the way to use vmaf
This article was originally published on OTTVerse as “EasyVMAF: Running VMAF In The Wild”.
VMAF is one of the most popular tools for video quality assessment, and it is well on its way to becoming a standard reference metric for the video industry. However, running VMAF can get tricky in some situations and lead to wrong results. In this article, we introduce easyVMAF, a tool we developed to make VMAF computations easier and more straightforward.
VMAF is a full reference metric that compares the reference (or source) and distorted video sequences to predict the subjective video quality.
The advantage of VMAF is that it seeks to mimic the viewer’s perception (i.e., the human visual system) instead of relying on purely objective metrics such as PSNR or SSIM. For an in-depth explanation of VMAF, please read the official Netflix blog.
Several 3rd-party tools have been built on top of VMAF with the participation of the open-source community. As a result, VMAF is available via several open-source packages such as the VMAF Python library, vmafossexec (C executable), a VMAF Docker image, libvmaf (C library), and FFmpeg compiled with libvmaf.
Note: Installation procedures for FFmpeg and VMAF, and a usage guide, are available on OTTVerse.com.
Despite the number of tools available to compute VMAF, it is often challenging to meet the strict set of requirements that VMAF imposes. Some of these requirements are:
- The reference and distorted videos need to be frame-synchronized. The scan mode (interlaced/progressive) has to match, they have to have the same duration, and they have to have the same frame rate.
- The reference and distorted videos’ resolution has to match, which often requires a robust up/downscaling procedure.
Hence, in practice, the videos have to be normalized when the reference and distorted videos do not meet the above-mentioned requirements.
In this tutorial, we go through a series of recommendations, using FFmpeg-based examples, that show how to normalize your streams before using VMAF. Finally, we introduce easyVMAF, an open-source tool that automates your VMAF computations.
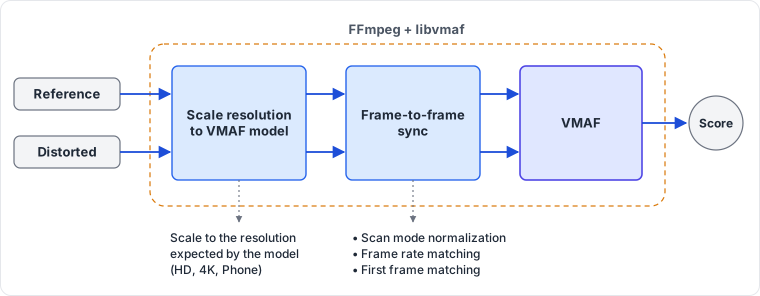
Figure 1. Normalization steps before VMAF: both inputs are first scaled to the resolution expected by the VMAF model and then frame-synchronized, all inside FFmpeg with libvmaf.
In the next sections, we tackle the basics of (i) scaling videos, (ii) frame synchronization, and (iii) finally, we talk about easyVMAF.
To keep the article’s length reasonable, we show only basic examples. For complete use cases, please head over to https://github.com/gdavila/easyVMAF.
Without further ado, let’s get started!
Scaling Video Resolution to the Right VMAF Model
The available VMAF implementations support three models: HD, 4K, and Phone.
Each model was trained by the team at Netflix considering different scenarios, such as screen size, resolution, and the viewer’s distance from the display device.
Accordingly, the VMAF specifications require that the video resolution matches the resolution expected by each model (refer to the first FAQ here):
- The HD and Phone models require
1920x1080video as their inputs. - The 4K model requires
3840x2160as its input.
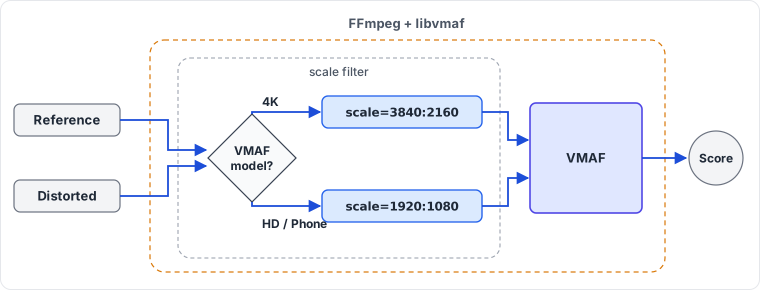
Figure 2. The target resolution is set by the VMAF model, not by the inputs: 3840x2160 for 4K, 1920x1080 for HD and Phone.
The resolution mismatch between the source and destination videos can be solved using bicubic interpolation in FFmpeg’s scale filter.
For example, to use the HD model (VMAF_v0.6.1.pkl), we need to scale the distorted video (if it isn’t 1920x1080) using the following FFmpeg command:
1
ffmpeg -i <distorted> -i <reference> -lavfi "[0:v]scale=1920:1080:flags=bicubic[distorted];[distorted][1:v]libvmaf=model_path=/usr/local/share/model/VMAF_v0.6.1.pkl" -f null -
Similarly, to use the 4K model, we need to scale the distorted video to 3840x2160:
1
ffmpeg -i <distorted> -i <reference> -lavfi "[0:v]scale=3840:2160:flags=bicubic[distorted];[distorted][1:v]libvmaf=model_path=/usr/local/share/model/VMAF_4k_v0.6.1.pkl" -f null -
The above examples assume that the reference video already matches the resolution expected by the VMAF model.
If that is not the case, you can apply the same scale filter to the reference as well:
1
ffmpeg -i <distorted> -i <reference> -lavfi "[0:v]scale=3840:2160:flags=bicubic[distorted];[1:v]scale=3840:2160:flags=bicubic[reference];[distorted][reference]libvmaf=model_path=/usr/local/share/model/VMAF_4k_v0.6.1.pkl" -f null -
Frame Synchronization
VMAF requires frame alignment between the reference and the distorted videos, so you have to guarantee that the frame rates, scan mode, and video durations match.
Here is how you can achieve frame alignment.
Scan Mode Mismatch
H.264/AVC live sources are traditionally set to interlaced scan mode, but once they go through an OTT transcoder, the output is typically progressive. So, if we want to compute VMAF, we first need to normalize the scan mode.
Given that the VMAF models were trained with progressive scan mode, we suggest always deinterlacing the interlaced inputs.
The scan mode can be normalized in FFmpeg using the yadif filter:
1
ffmpeg -i <distorted> -i <reference> -lavfi "[1:v]yadif=0:-1:0[ref];[0:v][ref]libvmaf=model_path=/usr/local/share/model/VMAF_v0.6.1.pkl" -f null -
The above command line assumes that the reference stream is interlaced, so it is passed to the yadif filter with the options mode:parity:deint = 0:-1:0. This means:
0: Output one frame for each frame in the input.-1: Enable automatic detection of field parity.0: Deinterlace all frames.
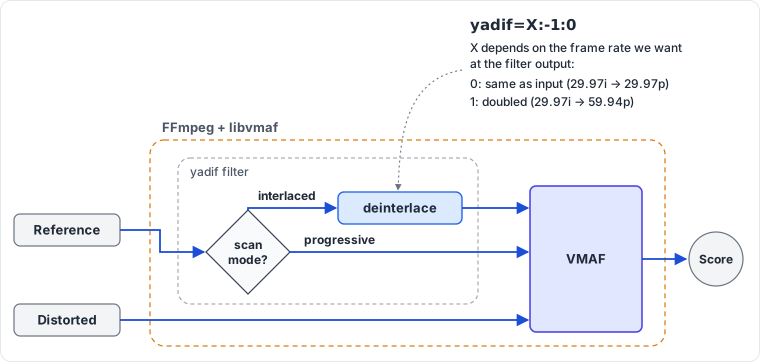
Figure 3. Scan mode normalization: only the interlaced input goes through yadif, and the first yadif option sets whether the output keeps or doubles the input frame rate.
So, if the filter input has a frame rate of 29.97i (interlaced scan mode), the yadif filter outputs 29.97p in progressive mode.
This is the most typical conversion for interlaced sources, but you can also experiment with other options. For example, yadif=1:-1:0 produces a 59.94p output for the same input.
Frame Rate Mismatch
First, you need to know that VMAF was not trained to deal with frame rate conversion, so here we force the inputs to artificially work with VMAF.
Accordingly, the scores should be used cautiously and not as fully reliable values.
Still, computing even this biased score can be useful because, in practice, frame rate conversion is pretty common on ABR ladders.
Here again, to force the frame rate conversion we use another FFmpeg filter:
1
ffmpeg -i <distorted> -i <reference> -lavfi "[0:v]fps=fps=30[distorted];[distorted][1:v]libvmaf=model_path=/usr/local/share/model/VMAF_v0.6.1.pkl" -f null -
The fps filter sets the frame rate by adding new frames (i.e., duplicating frames) or discarding them until the desired value is reached.
We prefer to leave the reference unmodified and apply the filter only to the distorted video.
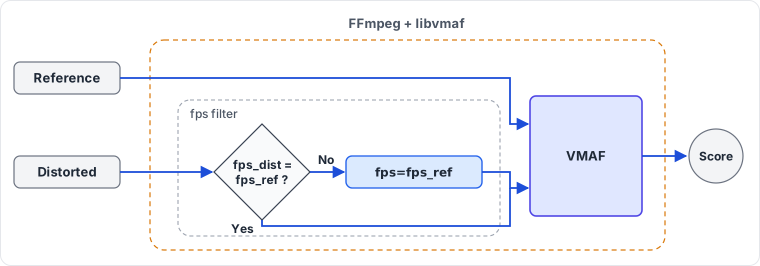
Figure 4. Frame rate adaptation: the reference is left unmodified, and the distorted video is converted with the fps filter only when its frame rate differs from the reference.
First Frame Mismatch
Sometimes, the reference video may start at a different frame than the distorted sequence.
This “starting-frame” mismatch results in a drift between the two sequences and leads to wrong VMAF scores.
To correctly compute the VMAF scores, we need to align the first frames of both the reference and distorted videos. One way to do so is to trim the misaligned video sequence until we achieve frame alignment.
We can trim the videos using FFmpeg’s trim filter, which guarantees that the output contains a continuous subset of the input.
But first, we need to determine the starting point and duration of the subset of frames that match in both the reference and distorted sequences. The challenge here is to find the right starting point to pass to the trim filter.
To solve this, we propose a PSNR-based approach that iteratively computes the PSNR between the distorted and reference videos until a match is found.
Here are the details:
- First, we extract two video samples consisting of the first m frames of the distorted and reference sequences and compute the PSNR between them. This is the PSNR of the first iteration. We suggest using only a small number of frames (i.e., m) to reduce the computational cost.
- In the second iteration, we slide the distorted subsample forward by one frame and compute the PSNR again.
- This process of “sliding and computing the PSNR” is repeated n times, where n is the number of video frames that fit in the SyncWindow. The SyncWindow is the duration in which we want to find the right sync value.
- If we are lucky (i.e., if the SyncWindow was chosen correctly), at the end of the process the best PSNR is found on some i-th frame. That means that the i-th frame of the distorted sequence matches the 1st frame of the reference.
At the end of this process, we have enough information to apply the trim filter.
The iterations described above are shown in Figure 5. On each iteration i, the PSNR is computed between the reference_subsample and the distorted_subsample_i.
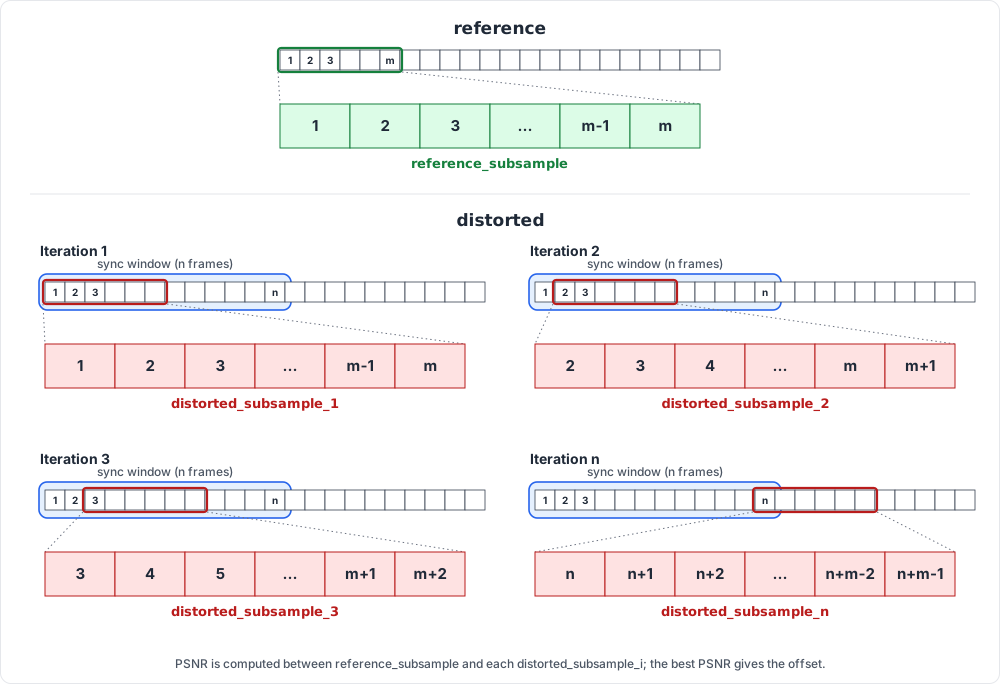
Figure 5. First frame alignment: the reference subsample (first m frames) is fixed, while the distorted subsample slides one frame per iteration inside a sync window of n frames. The values of m and n are symbolic.
In practice, the PSNR calculation at each iteration can be done as follows:
1
2
3
     while <distorted_subsample_i.1st_frame> IN <SYNC_WINDOW>:
         getPSNR(reference_subsample, distorted_subsample_i)
     <distorted_subsample_i>.next_frame()
And the getPSNR() function can be implemented with FFmpeg as follows:
1
2
3
4
 ffmpeg  -i <distorted> -i <reference> \
 -lavfi "[0:v]trim=start=<OFFSET>:duration=<M>,setpts=PTS-STARTPTS[distorted_subsample];\
 [1:v]trim=start=0:duration=<M>,setpts=PTS-STARTPTS[reference_subsample];\
 [distorted_subsample][reference_subsample]psnr=stats_file=psnr.log" -f null -
where:
1
2
3
 <OFFSET>: (i-1)*1/fps, and fps is the framerate per second.
 <M>: Size in seconds of the subsample sequence. This is a fixed value for all the iterations.
 <SYNC_WINDOW>: window time (seconds) in which we want to find the right sync value
For instance, if we choose <SYNC_WINDOW> = 0.3 seconds for video sequences at 30 fps, we get something like this:
1
2
3
4
5
6
7
8
9
10
11
 iteration    offset(s)                   psnr[dB]
   1          0.0                         21.098356
   2          0.03333333333333333         21.132783
   3          0.06666666666666667         21.167991
   4          0.1                         21.204151
   5          0.13333333333333333         21.248292
   6          0.16666666666666666         21.29118
  *7          0.2                         33.675342
   8          0.23333333333333334         21.363845
   9          0.26666666666666666         21.409776
   10         0.3                         21.451546
Based on these values, the best PSNR was found on the 7th iteration.
So, the 7th frame of the distorted sequence (located 0.2 seconds from its start) matches the 1st frame of the reference sequence.
With this information, we can trim the sequence and compute VMAF using FFmpeg:
1
ffmpeg -i <distorted> -i <reference> -lavfi "[0:v]trim=start=<OFFSET>,setpts=PTS-STARTPTS[distorted];[distorted][1:v]libvmaf=model_path=/usr/local/share/model/VMAF_v0.6.1.pkl" -f null -
In practice, we sometimes also need to pass the duration parameter to trim (trim=start=<OFFSET>:duration=<LENGTH>) to guarantee that the distorted and reference sequences have the same length in seconds.
Putting It All Together using easyVMAF
So far, we have discussed how to pre-process your videos before computing VMAF using a few simple examples.
However, in practice, it is pretty common to apply all or most of the normalizations described above at the same time, i.e., upscale, deinterlace, change the frame rate (for example, from 29.97 to 30 fps), and synchronize the distorted and reference frames in the time dimension.
Instead of performing these steps manually, the entire process is automated in easyVMAF, a Python script that completes the normalization processes required by VMAF.
easyVMAF uses FFmpeg and FFprobe for all the necessary video editing and information gathering. It performs deinterlacing, up/downscaling, frame synchronization, and frame rate adaptation.
Figure 6 shows a high-level overview of easyVMAF.
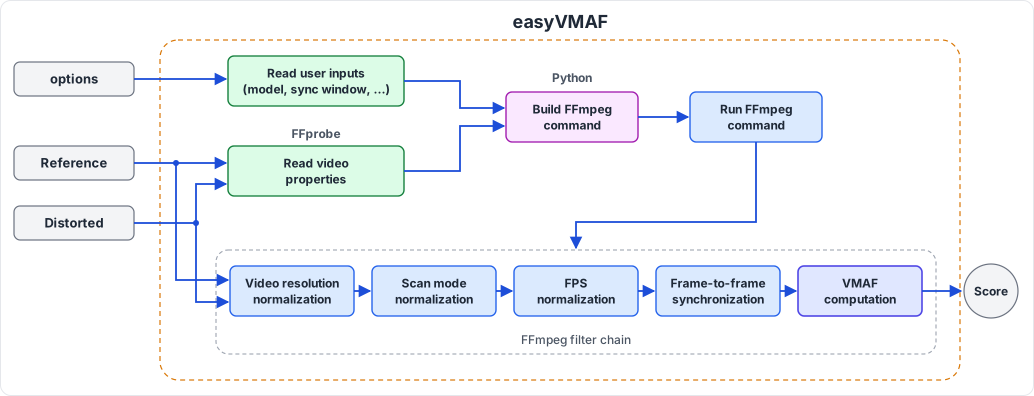
Figure 6. easyVMAF architecture: the Python script gathers the user options and the FFprobe video properties, then builds and runs a single FFmpeg command whose filter chain performs every normalization step and the VMAF computation.
If you are curious about easyVMAF, please go to the GitHub repo, where you can check out a Docker image or browse through the source code.
Please check it out and try it on your videos! If you have any suggestions or improvements, or you want to contribute, feel free to submit PRs.
Before we end this article, here is the procedure for running the Docker image and an explanation of the command-line parameters:
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
 docker run --rm  gfdavila/easyVMAF -h
 usage: easyVMAF [-h] -d D -r R [-sw SW] [-ss SS] [-subsample N] [-reverse]
                 [-model MODEL] [-phone] [-verbose] [-output_fmt OUTPUT_FMT]
 Script to easily compute VMAF using FFmpeg. It allows to deinterlace, scale, and sync Ref and Distorted video samples automatically:
       Autodeinterlace: If the Reference or Distorted samples are interlaced, deinterlacing is applied
       Autoscale: Reference and Distorted samples are scaled automatically to 1920x1080 or 3840x2160 depending on the VMAF model to use
       Autosync: The first frames of the distorted video are used as a reference to do sync lookup with the Reference video.
            The sync is doing by a frame-by-frame lookup of the best PSNR
 See [-reverse] for more options for syncing
 As output, a json file with the VMAF score is created
 Optional arguments:
   -h, --help            show this help message and exit
   -sw SW                Sync Window: window size in seconds of a subsample of the Reference video. The sync lookup will be done between the first frames of the Distorted input and this Subsample of the Reference. (default=0. No sync).
   -ss SS                Sync Start Time. Time in seconds from the beginning of the Reference video to which the Sync Window will be applied from. (default=0).
   -subsample N          Specifies the subsampling of frames to speed up calculation. (default=1, None).
   -reverse              If enabled, it Changes the default Autosync behaviour: The first frames of the Reference video are used as reference to sync with the Distorted one. (Default = Disable).
   -model MODEL          VMAF Model. Options: HD, HDneg*, 4K. (Default: HD).
   -phone                It enables VMAF phone models (HD only). (Default=disable).
   -verbose              Activate verbose loglevel. (Default: info).
   -output_fmt OUTPUT_FMT
                         Output VMAF file format. Options: json or xml (Default: json)
 required arguments:
   -d D                  Distorted video
   -r R                  Reference video
 * NOTE: HDneg is a VMAF experimental feature not supported yet by FFmpeg.